Service questions deserve attention
55.5% of captured mentions carry a negative label. Review the underlying experience before drawing a conclusion.
A leadership perspective on municipal and housing experiences
The captured conversation points to practical opportunities in service ownership and local communication.
5,617 mentions · platform labels, reviewed in context
55.5% of captured mentions carry a negative label. Review the underlying experience before drawing a conclusion.
Selected housing and municipal examples describe repeated contact or uncertainty over who should act.
Repeated public-space messages show distribution. They do not by themselves prove independent endorsement.
The business value is a shorter path between a public signal and a well-informed leadership question. This snapshot supports a focused review of beneficiary journeys. It does not establish overall satisfaction, case resolution or the performance of an individual municipality.
Prioritize a small number of service questions that leadership can verify and act on.
Review the selected follow-up journeys and agree one owner for each next update.
Pair a public-space announcement with local access information and delivery milestones.
Publish a weekly evidence brief with an explicit question and proposed next step.
These roles are proposed responsibilities, not confirmed assignments. The first meeting should select a sponsor and agree the service perimeter. The aim is a repeatable decision process with clear evidence and follow-through, rather than a larger volume of reports.
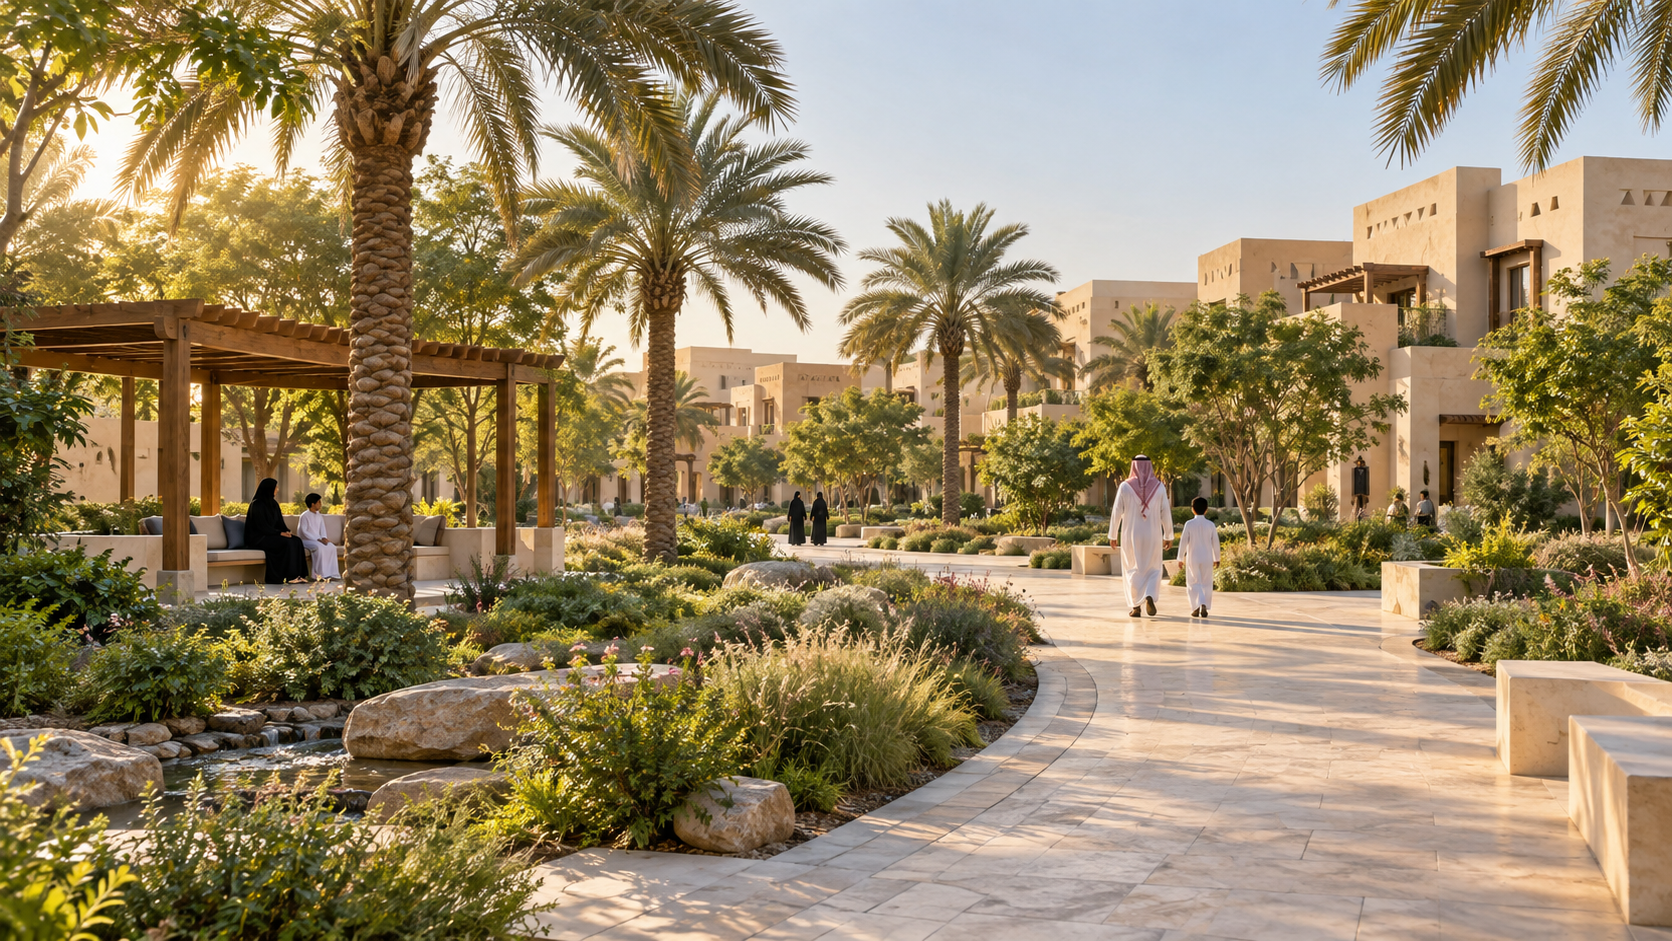
MOMAH’s September announcement connects public spaces with easier movement and more accessible neighborhoods.
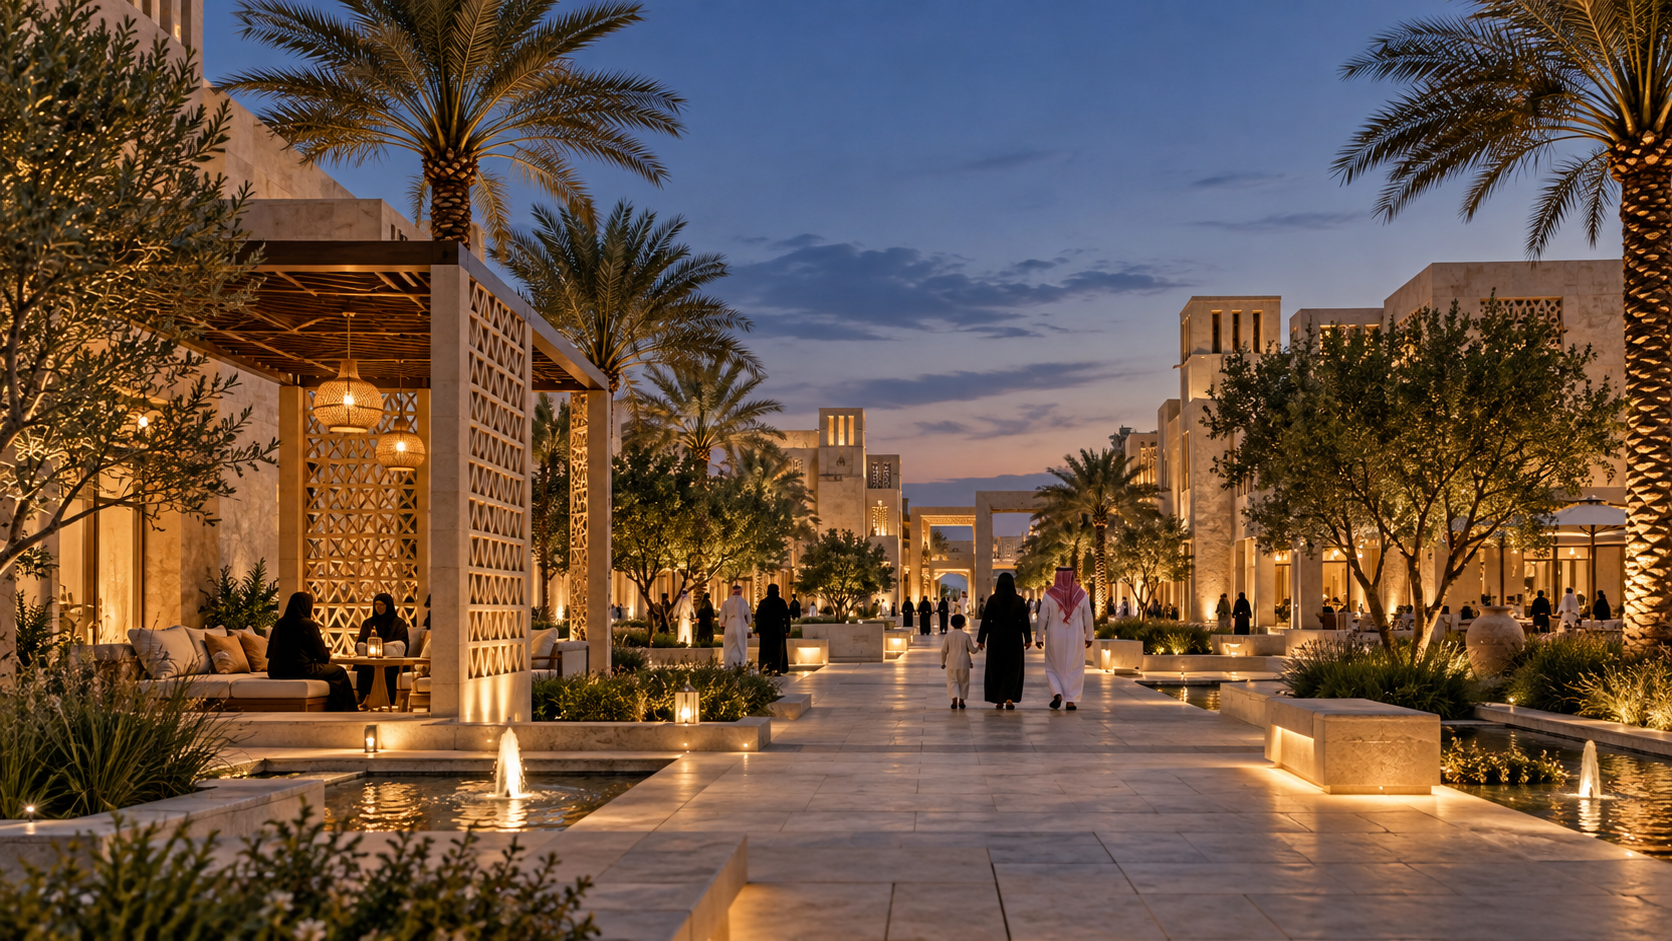
MOMAH · H1 2026 delivery · published 29 September 2026
The figures describe the first half of 2026, as published by MOMAH on 29 September.
Where can communication help residents understand access, local delivery and the next milestone?
The official portal positions Balady and Sakani as key service channels. The recommended intelligence approach connects that strategic ambition to concrete questions about the beneficiary journey. The public conversation is one source of evidence alongside operational records and direct feedback.
MOMAH-topic listening collected in ACME, downloaded on 29 September 2026.
1–30 September 2026. The snapshot precedes month-end and is not a completed September report.
Almost all mentions come from X. Findings describe this topic and source coverage.
Each conversation export stops at 100 rows. Selected examples explain issues without estimating prevalence.
Twenty-four exported widgets cover totals, sentiment, themes, hashtags and audience attributes. Their scopes differ. Some exclude unknown locations or neutral sentiment. Every exhibit therefore retains its own denominator, time zone and coverage statement.
Every chart needs its own denominator. The full conversation is larger than the attributed audience subsets.
Common visual scale: 5,617 topic mentions. Subsets overlap and are not additive.
These are counts of mentions in returned widget rows. They are not counts of residents, cases or service users.
A missing attribute limits the analysis. It does not establish a characteristic of the people who are missing.
For leadership, the most useful comparison is between the question and the evidence available to answer it. Topic volume and sentiment cover 5,617 mentions. Country, gender and age widgets return different subsets. The age widget includes an explicit uncategorized row, while other absent mentions are simply outside its returned total. Preserve those distinctions when writing a brief. Request an aligned retrieval only when a decision depends on the missing coverage.
Weekly buckets describe the returned snapshot. The absent week remains a gap.
Week starting · Asia/Riyadh · first and final buckets cover partial weeks
The buckets beginning 31 August and 7 September contain 2,464 and 2,603 mentions.
The missing 21 September bucket and partial final week prevent a reliable conclusion about momentum.
The first bucket begins before the configured window because the widget groups by week. It is still bounded by the September query. The absence of a returned row does not prove zero conversation. The chart deliberately uses separate columns rather than a line across the gap.
The exported reach metric totals 81.42 million. Returned engagement rows sum to 10,157.
Week starting · Asia/Riyadh · first and final buckets cover partial weeks
Aggregated reach can include repeated exposure. Do not interpret it as population coverage.
Use the dashboard to switch between mentions, reach and engagement without mixing scales.
The reach total reconciles to the four returned weekly rows. Engagement is a separate sum from the same trend widget. Neither measure demonstrates behavior change or completed services. A future evaluation should connect communications objectives to an appropriate outcome measure rather than infer impact from exposure alone.
The four returned buckets sum to 10,157 engagements. The missing week remains a gap.
Week starting · Asia/Riyadh · first and final buckets cover partial weeks
The week beginning 7 September returns 5,141 engagements, the largest observed bucket.
An engagement count cannot confirm whether a question was answered or a service journey improved.
Use the observed concentration to select material for review: which messages attracted attention, which questions followed, and whether the content gave a usable next step. Keep engagement separate from reach and sentiment. A highly visible message can still leave a practical question unresolved. Do not interpret the smaller final bucket as declining interest because the snapshot cuts the period short and another week is absent.
3,118 of 5,617 captured mentions carry a negative classification.
Courtesy, quoted replies and sarcasm can change what a sentiment label appears to mean.
Review the recurring experience, verify the underlying case and identify the question an owner can resolve.
The positive, neutral and negative totals reconcile to 5,617. These are platform classifications within captured conversation, not a survey of Saudi residents. A reviewed example in the positive export criticizes a service reply sarcastically. Its label remains in the source data, while the interpretation is flagged separately.
Dubai-time observations include positive and negative mentions only. Neutral and uncategorized records are excluded.
1,439
481
1,425
647
174
34
—
—
93
104
Terracotta: negative. Green: positive. 21 September is missing, not zero. Neutral is excluded.
The returned trend contains 3,131 negative and 1,266 positive mentions.
The negative total is 13 above the summary. Time zone and scope differ, but the export does not prove the cause.
The first two observed buckets contain most of the returned activity in this series. A missing 21 September row and partial boundary weeks prevent a complete month narrative. The comparison is descriptive, not a conclusion about sentiment improving or deteriorating. If MOMAH needs a reliable change measure, retrieve both periods with the same source filters, time zone and sentiment treatment, then inspect the messages behind the shift.
5,615 of 5,617 mentions come from X. Facebook and news each contribute one returned mention.
X: 99.96% of 5,617 mentions. The two small rows remain labeled at their actual value.
The findings describe an X-led conversation, rather than a balanced cross-channel view.
Use public posts to identify questions. Use operational records to establish the actual service response.
Channel concentration matters when leaders ask how representative the findings are. People who contact a call center, use an app, visit a service office or choose not to post are not represented by this source mix in a measurable way. The listening snapshot can point to a journey worth reviewing. Triangulate it with the relevant beneficiary-care and service records before drawing a wider conclusion about experience.
Arabic accounts for 96.2% of captured mentions. Smaller language rows remain visible in the breakdown.
Denominator: all 5,617 mentions. Other languages total 42.
Explain the next action, responsible party and update point in plain language.
A language label describes the captured message. It is not a demographic or citizenship measure.
This distribution supports an Arabic-first briefing and review workflow for the captured topic. It does not remove the need for accessible alternative channels or other languages when the actual service journey requires them. The unknown-language category contains 109 mentions. Inspect short replies, links and mixed-language posts before assuming that every classification reflects the language a beneficiary would prefer for service.
The strongest communication lens is Arabic. Geographic conclusions need a narrower denominator.
96.2% Arabic-language mentions · Country coverage is not a city service map.
5,405 of 5,617 mentions are Arabic. Language is not a nationality measure.
The country widget returns 2,110 mentions, including 1,822 assigned to Saudi Arabia.
Unknown countries are excluded from the geography widget. The remaining 3,507 mentions are outside that returned country breakdown. Country attribution does not establish where a service incident happened. These data do not support municipality rankings or a map of local service performance.
Saudi Arabia accounts for 1,822 of 2,110 country-attributed mentions, or 86.4% of that subset.
Denominator: 2,110 attributed mentions. Another 3,507 mentions are outside this widget.
The Saudi share is 32.4% of all 5,617 mentions when the full topic is used as the denominator.
A source country attribution cannot confirm which municipality or housing project a post concerns.
There are 3,507 mentions outside the returned country breakdown. For place-based action, the location described in the source and the service record matters more than an account-level country label. Confirm the neighborhood, project or responsible authority before assigning an issue. This export does not support a municipality league table, a city-level heat map or a population sentiment estimate.
The gender widget returns 3,641 classified mentions. It is an attributed subset, not a census of beneficiaries.
Platform-attributed message counts. These are not verified identities or unique people.
A further 1,976 topic mentions are outside this returned breakdown.
Use the chart to understand evidence limits. Validate service needs through the actual beneficiary journey.
The returned rows sum to 2,909 male-classified and 732 female-classified mentions across sentiment labels. These are message counts attached to platform attributes, not verified identities or unique people. Differences in who posts and which profiles are classifiable can affect the result. The practical leadership implication is to avoid generalizing this subset to all residents or using it to prioritize individual access to services.
Only 889 mentions sit in a named age band. Another 3,514 are explicitly uncategorized in the age widget.
Full topic: 5,617 mentions. Named bands: 889. Returned age widget: 4,403.
The age widget returns 4,403 mentions in total. Another 1,214 topic mentions are outside its returned rows.
The content of a service question is more useful here than an inferred age category.
The 18–35 category is the largest named band, but its 681 mentions should not be read as evidence that most beneficiaries are young. Both the uncategorized group and the out-of-scope remainder are larger. A leadership report should show the evidence gap explicitly and avoid using this chart to estimate the age distribution of MOMAH service users.
Technology, entertainment and social media lead the returned interest labels. These rows can overlap.
Associated mentions. Categories may overlap and cannot be summed as unique audience.
The chart reports the ten largest returned labels. Do not add them as unique people or a population share.
Review whether clear service guidance travels alongside lifestyle and public-space discussion.
These labels can help an analyst choose examples for closer reading, but they are not sufficient to define audience segments or predict service needs. The counts refer to mentions associated with returned interest categories. A useful communications experiment would test whether a practical explanation answers an observed question, using an agreed outcome measure rather than assuming an interest label predicts behavior.
Selected examples connect public-space ambition with the experience outside the front door.
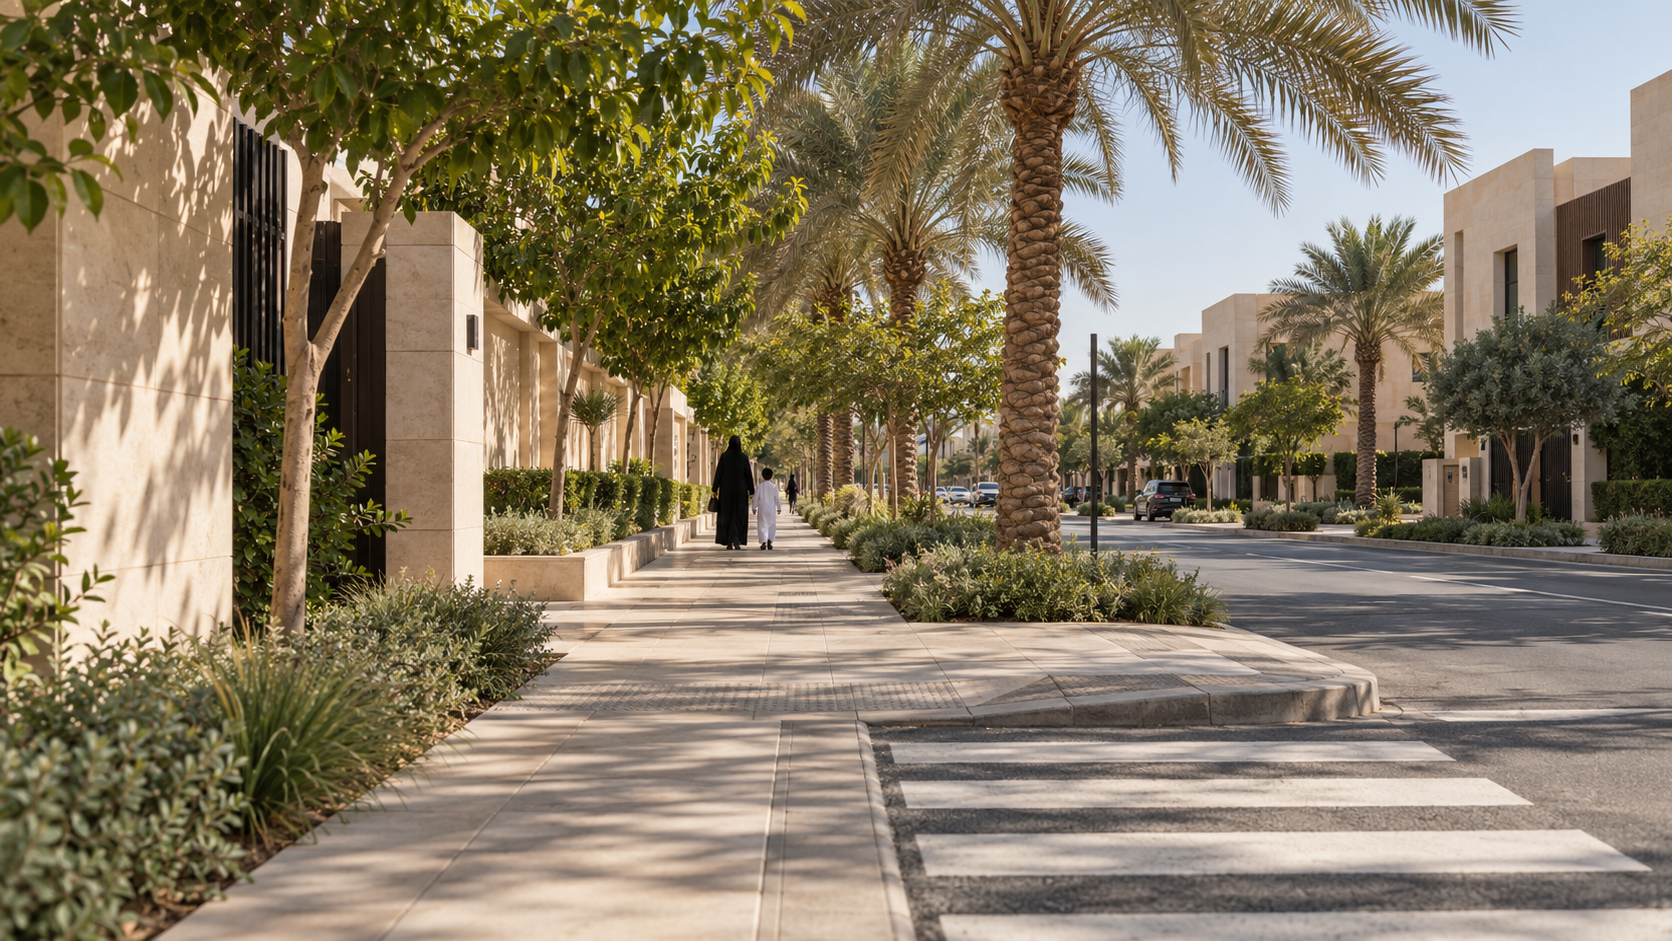
A recurring message asks why residents need a car to reach a place designed for walking.Read the original source ↗
A repeated message questions the need to drive to a walkway.
Another resident asks about lighting and waste containers in an occupied neighborhood.
These examples suggest a useful leadership question: does communication explain how residents can use an improvement, or only announce that it exists? A locality-specific update can make the delivery stage, access arrangements and next milestone visible. Operational teams should verify location and responsibility before making commitments.
A neighborhood improvement becomes easier to understand when the next milestone is visible.
A resident asks when a neighborhood will benefit from announced quality-of-life improvements.Read the original source ↗
Selected posts ask about missing essentials, access to walking routes and expected greening work.
Location, project scope, responsible entity and delivery status require operational records.
Compare a general announcement with a locality-specific update that explains the next step.
An insights team can group related examples before requesting a review. A service owner can then confirm whether they refer to one project or different responsibilities. This avoids treating every repeated mention as a separate incident, or assigning a complaint to a municipality solely because an account was tagged.
Selected housing messages describe follow-up questions that cross organizational boundaries.
A beneficiary describes being referred between a bank and a housing-support body over a payment question.Read the original source ↗
Examples include requests for a complaint update and a reservation-payment follow-up.
One beneficiary describes referrals between a bank and a housing-support body.
Public posts are evidence of an expressed experience, not proof of case status or fault. The proposed response is to verify the internal record, identify one follow-up owner and tell the beneficiary what will happen next. A brief thank-you message should not be treated as evidence of case closure.
Service communication should distinguish acknowledgement, progress and a confirmed outcome.
A brief message thanks the housing-care account. It does not establish that the underlying matter was resolved.Read the original source ↗
Was the concern received and understood?
Does the beneficiary know who owns the next step?
Does the operational record confirm what was completed?
The selected thank-you message is useful precisely because it shows the limit of interpreting tone alone. A polite reply may reflect courtesy, a helpful explanation or a resolved issue. Public text cannot distinguish these reliably without additional context. The proposed brief should record the confirmed outcome separately from the sentiment label.
Positive examples include community appreciation, public-space content and constructive urban suggestions.
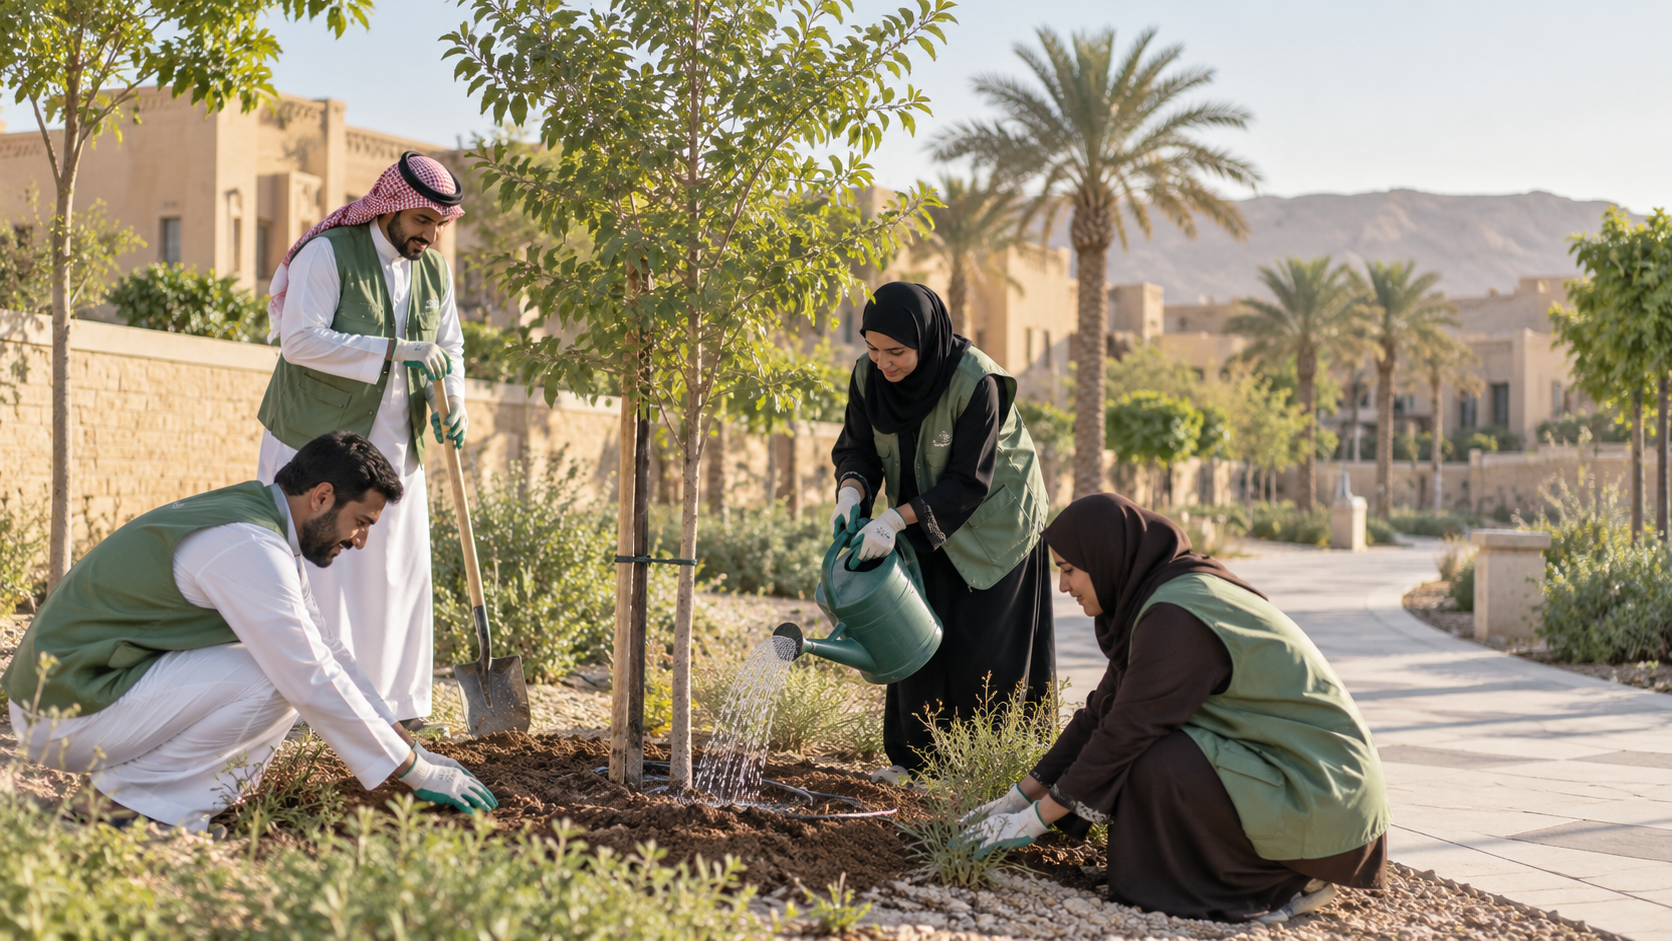
A captured message praises a local volunteer team and its progress.Read the original source ↗
Show a verified improvement, its location and how residents can benefit.
Explain the next step for recurring service questions in plain language.
Invite specific observations through the appropriate service channel.
The communication opportunity is to connect announced progress with recognizable beneficiary experiences. Community stories should use verified outcomes and appropriate permissions. Constructive suggestions should remain visible even when the platform groups them with positive content.
One public-space message repeats in 62 of the 100 rows in the positive conversation export.
A capped sample, not the 1,266 positive mentions. Repetition does not prove coordination.
Repeated wording is evidence of message distribution across captured posts.
Independent reactions, useful responses and verified beneficiary outcomes require separate measures.
The duplicate count uses exact text after removing links and normalizing whitespace. It applies only to the 100-row positive export, not all positive mentions. This comparison does not allege inauthentic behavior. Municipal accounts may legitimately distribute the same campaign message. Hashtags can co-occur in one post and must not be added as unique people or unique messages.
The leading returned hashtags connect municipal place, national vision and digital-service themes.
Top 10 of 414 returned hashtag rows. Co-occurring tags make these counts non-additive.
Equal counts across several digital-service hashtags can reflect the same messages carrying those hashtags together.
Hashtag frequency alone does not show a separate issue, an independent endorsement or a service outcome.
The hashtag export contains 414 returned rows. This chart shows the ten largest by mention count and preserves the original Arabic spellings. For communication planning, select a tag and inspect its source messages before inferring why it is prominent. Do not add rows together as topic volume, and do not treat a regional hashtag as proof of the author’s location or the location of a reported service issue.
The leading three hashtags carry predominantly positive platform labels in the returned hashtag-sentiment widget.
Negative 2 · Neutral 1 · Positive 410
Negative 0 · Neutral 0 · Positive 402
Negative 0 · Neutral 5 · Positive 357
Each bar has its own denominator. Green = positive; gray = neutral; terracotta = negative.
Each stacked bar uses that hashtag’s returned sentiment counts. Rows overlap across posts.
Positive wording can reflect campaign distribution. Independent beneficiary response requires source review.
The positive-conversation sample provides a useful companion exhibit: 62 of its 100 rows repeat one public-space message after links and whitespace are normalized. That observation does not establish that these leading hashtags belong to the same posts. It shows why a communications brief should report reach, repetition and substantive response as different questions rather than collapsing them into one success measure.
Different widgets answer different questions. Their numbers must retain their original scope.
A message in the positive stream repeats a polite service reply and then criticizes that reply sarcastically.Read the original source ↗
Mentions use Riyadh time. The sentiment trend uses Dubai time and excludes neutral and uncategorized rows.
The two conversation exports each contain 100 rows. Keyword paging stopped after a repeated page.
Some messages are repeated, sarcastic or unrelated despite mentioning an official account.
The negative sentiment trend sums to 3,131, while the summary returns 3,118. These values are preserved separately. Different time zones are one observed scope difference, not a proven explanation of the discrepancy. No reconciliation is forced. An aligned retrieval and scope review are required before direct comparison.
The proposed operating response connects public signals to an accountable internal review.
Check the source, case context and relevant jurisdiction.
Name the team that owns the next substantive update.
Tell the beneficiary the next action and expected update point.
Check the outcome using operational evidence.
This is a proposed workflow rather than a description of MOMAH’s current process. It does not assume a service-level breach or a missing capability. The leadership discussion should establish where ownership is already clear, where partner journeys need coordination and which evidence can confirm completion.
The operating rhythm should serve an existing leadership decision.
Insights selects material observations, checks sources and records uncertainty.
Service owners confirm context. The sponsor selects a decision or verification step.
The owner records the outcome and the evidence needed for the next brief.
Routine observations can remain in the dashboard. A material issue enters the leadership brief when it changes a decision, requires coordination or warrants verification. This is a proposed cadence for the pilot, not a commitment to automated alerts or an assessment of MOMAH’s existing reporting process.
Prepared example based on this snapshot. Proposed actions require operational confirmation.
Selected housing posts describe repeated follow-up and referrals between parties.
Unclear ownership may prolong uncertainty even when a reply has been sent.
Nominate an owner to verify these journeys and recommend the next beneficiary update.
Case status, responsible party, substantive last contact and confirmed outcome.
A useful brief keeps the observation, interpretation and proposed action separate. It cites the source, states the limits of the sample and identifies what additional evidence can resolve uncertainty. The leadership sponsor can then ask for a decision, a verification step or no further action.
The dashboard suite connects the summary to inspectable evidence.
What stands out in the captured conversation?
Which service journeys deserve a closer review?
What do the returned metrics actually measure?
Where can clearer messages support the experience?
What question, owner and next step belong in the brief?
These views use the same frozen evidence as this report. They work offline and offer Arabic and English navigation. Source dialogs explain scope. Example filters affect only the curated examples, and prepared briefing answers are not a live AI service.
An approved AI assistant can use documented Sprinklr tools to research a question and retrieve supporting evidence.
Ask about a defined topic, source set and reporting period.
Documented tools support research, dashboard questions and cited-message retrieval.
An analyst reviews scope and interpretation before leadership uses the result.
Model Context Protocol is the connection between the approved assistant and the available Sprinklr tools. Workspace selection, access and enablement must be validated for a pilot. This package was prepared from exported data and public research. It does not demonstrate a live MOMAH connection, automatic case resolution or production write-back.
Agree a sponsor, an approved workspace and two service questions for the first cycle.
Set baselines for preparation time, source traceability and usefulness.
Produce a brief; record the share of claims with usable sources.
Repeat the questions and record review effort and usefulness.
Compare with baseline and decide whether to extend the scope.
Measure elapsed preparation time, the proportion of material claims with usable sources, and sponsor-rated usefulness on an agreed scale. Set acceptance thresholds with MOMAH in week one. Keep human approval of conclusions and any subsequent action. No saving, satisfaction improvement or ROI is promised in advance.
Agree the baseline and acceptance criteria before the first comparison. No result is assumed in advance.
| Measure | Week 1 | Weeks 2–3 | Week 4 |
|---|---|---|---|
| Preparation time | Baseline minutes | Record each cycle | Compare like tasks |
| Source traceability | Audit current claims | Sourced / reviewed claims | Review gaps |
| Leadership usefulness | Agree rating scale | Sponsor rating + reason | Decide scope |
Proposed measurement design. Blank baselines are intentional; no results or savings are invented.
Record the same question type, source scope and review standard each week.
A faster brief is useful only if its important claims can be checked and leaders can act on it.
Measure elapsed preparation time from question receipt to the approved brief. For traceability, divide material claims with usable supporting sources by all material claims reviewed. Ask the sponsor to rate usefulness using one agreed scale and record the reason for the score. The week-four decision should consider these results together, including exceptions and the analyst review effort, before expanding the scope.
Use each result with its source, unit, denominator and reporting boundary.
A returned topic-matching message. It is not necessarily a unique person, complaint or case.
The original platform classification. Analyst review does not overwrite the exported totals.
A reviewed, paraphrased source within the capped conversation exports.
A recommended action or operating model for discussion, not an observed outcome.
Rates use the displayed denominator and round to one decimal place unless stated otherwise. Duplicate grouping removes links and normalizes whitespace, then matches exact text. It does not infer coordinated behavior. Missing observations stay missing, and no confidence intervals or population estimates are derived from these exports.
Every quantitative exhibit traces to the supplied snapshot. Public context and product references are identified separately.
ACME workspace. 24 exported widgets. September query window, incomplete month.
Municipal and housing services, Balady and Sakani, and Vision 2030 context.
MOMAH reports over 667 km of walkways and sidewalks, 108 municipal squares and 44 parks. Historical delivery, not September listening results.
Internal Confluence, current v4. Positioning and roadmap reviewed through TWG. Roadmap is not a tenant availability guarantee.
Internal Confluence, current v5. Documents research, dashboard questions and retrieval of cited source messages. Access requires configuration.
The original exports remain unchanged. The package preserves units and denominators, leaves absent weeks unfilled and excludes unverified prior-period comparisons. Selected posts are paraphrased and linked. Proposed actions and pilot roles are recommendations for discussion.